Nvidia Vera Rubin MLPerf Debut: Up to 2x Faster Than Blackwell Ultra
Nvidia's Vera Rubin NVL72 posted the fastest time to train on six of seven MLPerf Training v6.1 tests, up to 2x faster per GPU than GB300.
Key points
- Nvidia's Vera Rubin NVL72 system made its MLPerf debut in the Training v6.1 results published on 16 November 2026.
- Nvidia says Vera Rubin delivered the fastest time to train on six of the seven benchmarks and up to 2x the per-GPU performance of an optimised GB300 NVL72 (Blackwell Ultra) system.
- On the DeepSeek-V3 671B benchmark, 1,024 Vera Rubin GPUs trained to target in 4.14 minutes, against 8.03 minutes for the same number of GB300 GPUs.
- CoreWeave says it was the only cloud provider to submit multi-rack Vera Rubin results, training DeepSeek-V3 in 17.65 minutes on 256 Rubin GPUs.
- Nvidia says 80 percent of closed-division submissions in the round ran on its platforms, across 20 partner organisations.
Nvidia’s next-generation Vera Rubin platform has posted its first official AI training benchmarks, and the company says it is up to twice as fast per GPU as its current Blackwell Ultra systems. In the MLPerf Training v6.1 results published on 16 November 2026, Nvidia says the Vera Rubin NVL72 rack set the fastest time to train on six of the seven tests, while cloud provider CoreWeave published the first multi-rack Vera Rubin results.
What happened?
MLPerf Training is a benchmark run by the MLCommons consortium. Hardware makers and cloud providers submit results showing how quickly their systems train a set of AI models to a fixed quality target. Version 6.1 has seven tests, ranging from small language models to a 671-billion-parameter mixture-of-experts model and a reinforcement learning task.
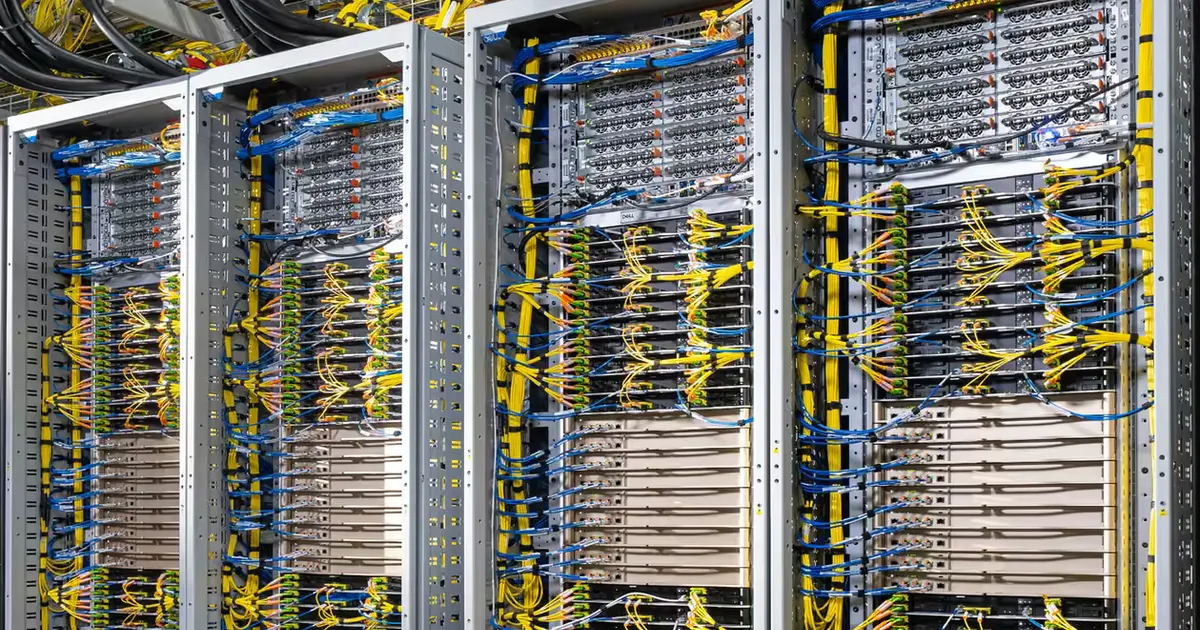
Vera Rubin NVL72 is Nvidia’s rack-scale system that links 72 Rubin GPUs with its Vera CPUs. This was its first appearance in the benchmark. According to Nvidia’s technical blog, the system “delivered the fastest time to train on six of the seven benchmarks”, with up to 2x the performance of a highly optimised GB300 NVL72 system, Nvidia’s Blackwell Ultra platform.
How much faster is Vera Rubin?
Nvidia compared Vera Rubin with GB300 NVL72 at the same number of GPUs. Its reported per-GPU speedups are:
| Benchmark | GPUs | Vera Rubin speedup vs GB300 |
|---|---|---|
| DeepSeek-V3 671B (pretraining) | 1,024 | 2x |
| gpt-oss 20B | 64 | 1.6x |
| Llama 3.1 8B | 72 | 1.6x |
| Llama 2 70B LoRA (fine-tuning) | 72 | 1.5x |
| FLUX.1 (image generation) | 72 | 1.5x |
| Qwen3.5 397B GRPO (reinforcement learning) | 64 | 1.4x |
| DLRMv4 (recommendation) | 128 | 1.4x |
The headline result is DeepSeek-V3. On 1,024 GPUs spread across 16 racks, Vera Rubin reached the target in 4.14 minutes, against 8.03 minutes for the same number of GB300 GPUs. Nvidia also says Vera Rubin kept above 97 percent scaling efficiency when going from 256 to 1,024 GPUs.
Nvidia’s older platform still holds the fastest absolute time of the round. A GB300 NVL72 cluster of 10,240 GPUs across 160 racks finished one test in 1.38 minutes. Nvidia says that, together, its platforms hold the fastest time on every benchmark in v6.1, and that it was the only company to submit results on all seven tests.
Nvidia also published faster “unverified” numbers from reruns on newer software, reaching up to 2.4x. Those have not been checked by MLCommons and are not part of the official results.
What did CoreWeave show?
CoreWeave, one of the largest AI cloud providers, submitted results on Vera Rubin and on the older GB200 NVL72. It says it was the only cloud provider to submit multi-rack Vera Rubin results in this round.
- DeepSeek-V3 671B: 17.65 minutes on 256 Rubin GPUs across four racks, against 48.40 minutes on 256 GB200 GPUs. CoreWeave calls this a 2.7x improvement.
- Llama 3.1 8B: 7.16 minutes on a single 72-GPU Vera Rubin rack, 1.9x faster than its GB200 result of 13.70 minutes. CoreWeave says this was the fastest 72-GPU submission of the round.
CoreWeave notes that its speed-up figures are its own calculations from the published results, not figures verified by MLCommons. Its comparison is with the older GB200, so the gaps are larger than Nvidia’s comparison with GB300.
Why does it matter?
Training time is a direct cost for AI labs. Halving the time to train a large model on the same number of chips means either lower bills or the chance to train bigger models with the same budget. The results give buyers an early, peer-reviewed look at Vera Rubin’s performance before wider deliveries.
They also show how dominant Nvidia remains in AI training. Nvidia says 80 percent of all closed-division submissions in the round ran on its platforms, across 20 partner organisations. The results arrive during a turbulent period at the top of the company, which is now led by interim chief executive Colette Kress, as we reported in our story on Jensen Huang’s resignation.
What happens next?
Full results from all submitters are published by MLCommons. The next test for Vera Rubin will be real-world deployments in cloud data centres such as CoreWeave’s, and whether rival chips from other makers appear in future rounds to challenge Nvidia’s lead.
Frequently asked questions
What is MLPerf Training?+
MLPerf Training is an industry benchmark run by the MLCommons consortium. It measures how long a system takes to train AI models, such as large language models and image generators, to a set quality target.
How much faster is Vera Rubin than Blackwell Ultra?+
In MLPerf Training v6.1, Nvidia says Vera Rubin NVL72 was 1.4x to 2x faster per GPU than an optimised GB300 NVL72 system at the same GPU count, with the 2x gain on the DeepSeek-V3 671B benchmark.
Which cloud provider submitted Vera Rubin results?+
CoreWeave submitted Vera Rubin NVL72 results across up to four racks and 256 GPUs, and says it was the only cloud provider with multi-rack Vera Rubin results in the round.
Sources
- Nvidia Vera Rubin
- Nvidia
- MLPerf
- CoreWeave
- AI training
- AI chips
PFM Today Newsroom · News Desk
The PFM Today Newsroom tracks developments across startups, AI, design, business and more. Stories are researched from primary sources and reputable outlets, written with AI assistance, and reviewed against our editorial policy before publishing. Read our editorial policy.